Figure 1: Steps in the ATLAS Data Processing Chain
+ +## Motivation +Therefore, it's immensely important to monitor the performance of all of these components and ensure that they remain performant and resource-efficient. Over the course of Google Summer of Code, I collaborated with the ATLAS Software Performance Optimisation Team (SPOT), which tracks numerous job-level and component-level metrics (e.g. RAM usage, CPU time, etc) between nightly builds of Athena using the [ATLAS Performance Monitoring Board](https://atlaspmb.web.cern.ch/atlaspmb) (PMB), and reports anomalies therein. However, the definition of an anomaly is fuzzy at best, and to complicate matters further, many metrics are noisy, have missing data, or exhibit frequent one-nightly-build regressions due to configuration issues, quickly remedied bugs and more. For example: +- A component-level metric suddenly worsens between nightly builds, degrading the performance of all jobs using that component. +- A job-level metric suddenly improves between nightly builds. Although this may just mean a component was optimised, it may also mean a bug was introduced. + +Figure 2: The anatomy of an example metric, and a process by which a SPOT member might identify anomalies therein.
+ +With dozens of jobs using tens of thousands of components, and dozens of metrics for each, this is just too much data for any human to analyse by hand, so an automated solution was needed. This is where I came in: incorporating an anomaly-detection step into the [existing SPOT performance monitoring pipeline](https://gitlab.cern.ch/atlaspmb/PerformanceMonitoring) which uses statistical and machine-learning techniques to detect, report and diagnose these anomalies, and issue alerts when appropriate. + +## Introductory projects: Screening task and OpenSearch exporter +Before I started on anomaly detection, I first familiarised myself with the codebase through two smaller projects. + +The first of these projects was my initial screening task as part of the GSoC selection process, where I used `prmon`, a HSF performance monitoring tool, to record the performance of a simulated process and identify anomalies in various metrics therein, such as PSS (proportional set size), wall time and more. This both introduced me to the metrics that I would be analysing over the subsequent weeks and to a number of statistical and machine-learning techniques (some of which were more effective than others) that would form the foundation for the later algorithms I would design in the GSoC project. For brevity, further detail is omitted here but [a write-up for the screening task](https://github.com/douglaslindsay/ATLAS-SPOT) can be found on my GitHub. + +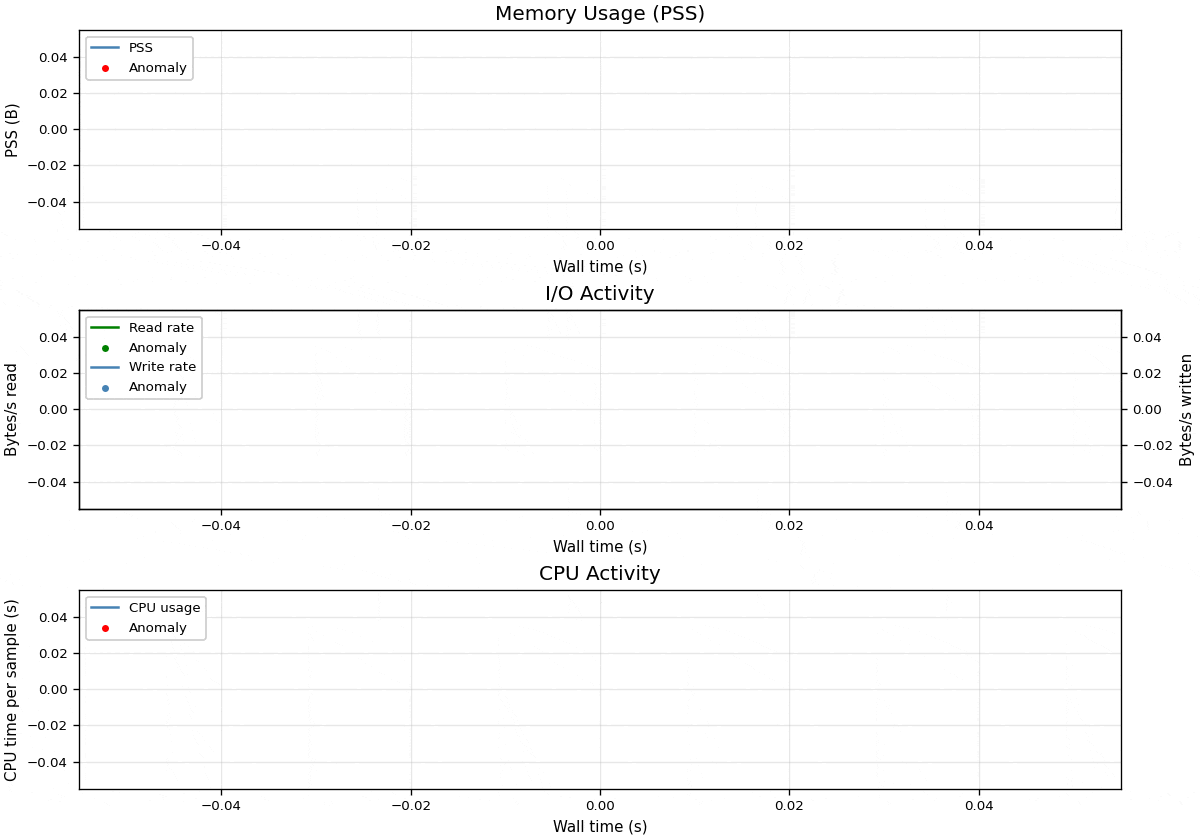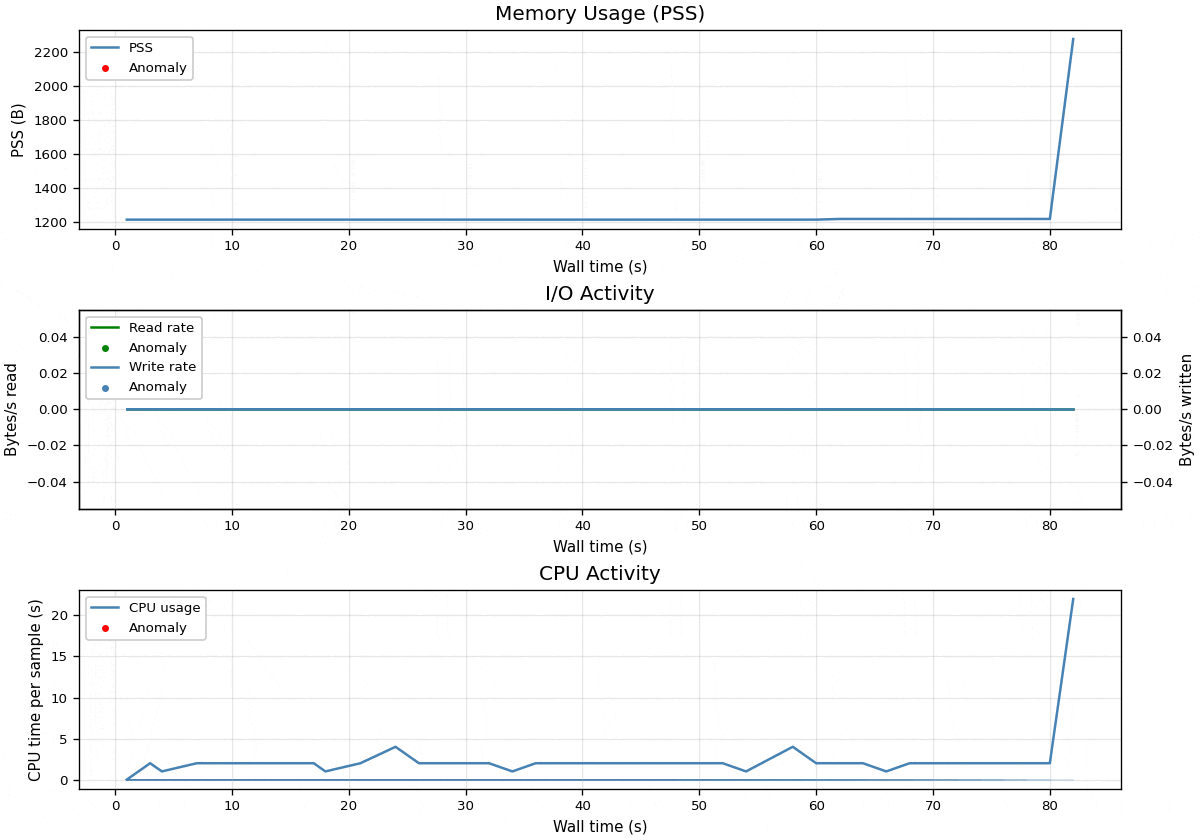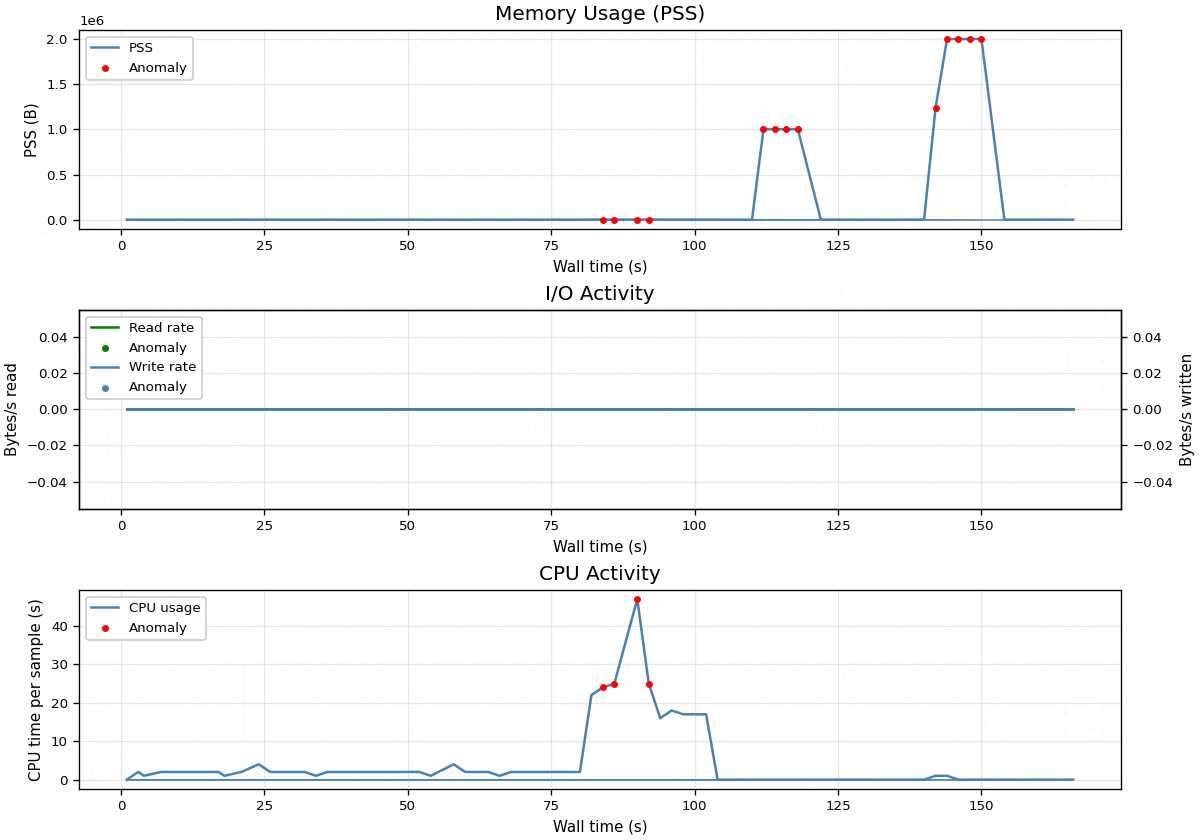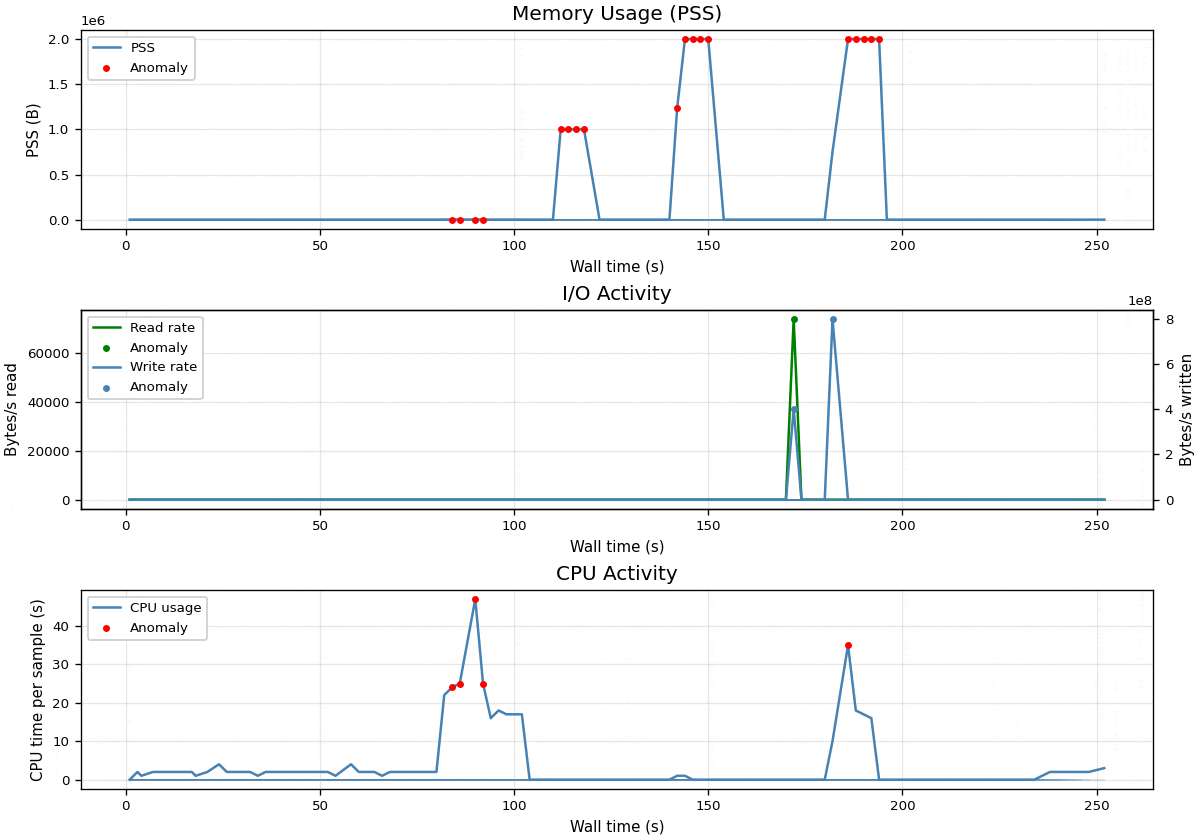
Figure 3: Real-time monitoring of prmon output and classification of anomalies.
Figure 4: Job-level metrics (illustrative only)
+Figure 5: Domain-level metrics (illustrative only)
+Figure 6: Component-level metrics (illustrative only)
+Figure 7: Stage-level metrics (illustrative only)
+Figure 8: A one-day regression versus a multi-day regression. When these regressions occur, they look exactly the same. But one’s anomalous, and one isn’t. How do we tell them apart?
+ +As shown in Figure 9, these were very effective at detecting deviations from normal performance, but were incapable of distinguishing between normal one-day regressions and anomalous persistent regressions, a problem I resolved by making both detectors wait a few days to confirm that a regression was persistent before reporting it (an anomalous persistent regression looks like a step change in a metric and therefore an impulse in its first derivative, so the two detectors identify the same phenomenon and are more likely to catch a false negative produced by the other), which is shown in Figure 10. I employed both the direct-metric and first-derivative univariate detectors in the final program. + +Figure 9: Output of one of the old univariate detectors, erroneously flagging a 1-day regression and noise as anomalies due to not waiting a few days before confirming.
+Figure 10: The same metric as shown in earlier figures, with both new univariate detectors successfully flagging the true anomaly but avoiding false positives by waiting a few days before reporting an anomaly.
+Figure 11: An example Mattermost message reporting anomalies, including some metadata about the job and each anomaly found in metrics therein.
+ +Additionally, I modified the script that creates the plots on the ATLAS Performance Monitoring Board so that it invoked my anomaly-detection script and included the detected anomalies on the plots for the PMB. + +#### Autonomous anomaly diagnosis +The last major piece of functionality I implemented was a routine that would attempt to connect job-level anomalies to their candidate root causes in the form of component-level anomalies, meaning that a high-level performance regression could have its source identified and resolved faster. For example, a job-level anomaly and a candidate component-level anomaly that potentially caused the job-level anomaly will typically have the same sign (except in the `cpu` edge case detailed below), allowing the root causes to be narrowed down. Job-level anomalies can be divided into three classes, and I implemented a distinct approach for each: +- Container size (`sizeperevt`): For a job-level anomaly in this class, the root-cause detection attempts to identify any domains of that job that themselves contain anomalies, and then any component-level anomalies (candidate root causes for the job-level anomaly) within those domains. +- Memory (`malloc`): For a job-level anomaly of this type, the root-cause detection attempts to determine what stage (`Initialize`, `First Event`, `Execute`, `Finalize` and `preLoadProxy`) a component-level anomaly might be found in using the stage the job-level anomaly was found in; if it did so successfully it filters component-level anomalies to only those within that stage. +- CPU (`cpu`): For this class of anomaly, the same procedure is followed as for `sizeperevt`, except it accounts for the fact that certain job-level metrics with units 1/s are inversely correlated with the component-level metrics, which are generally in units s. + +While this is imperfect, it is still a useful tool for narrowing down which components are responsible for observed regressions. + +#### Finishing touches +With the anomaly detection software essentially complete, the final weeks of the project were predominantly spent polishing it to produce the highest-quality result possible: +- Implementing a clean and concise CLI for each of the scripts +- Writing documentation for how the scripts should be used (e.g. `--help` messages) +- Typehinting all my software until it satisfied Pylance on Strict mode, and ensuring no partially-unknown types from external libraries like `pandas` or `matplotlib` were exposed. +- Incorporating my anomaly-detection script into the bash scripts comprising the performance monitoring pipeline +- Addressing various edge cases: + - Anomalies may occur in VMEM/PSS which are job-level `malloc` metrics but cannot be narrowed down to a specific stage: Resolved by not filtering by stage in this case. + - Historical nightly build timestamps in merged databases do not have a 1:1 correspondence with dates, because sometimes the pipeline fails and data is lost: Resolved by operating entirely in terms of nightlies with an associated date, rather than the other way around. + - Some metrics had a different name every day, causing data loss: Temporarily hardcoded an exception for these metrics and notified the team responsible and then, when this was resolved, removed that exception. + - Empty Mattermost reports would be produced if no anomalies were found: Resolved by not producing a report in these cases. +- Tuning parameters, e.g. the minimum standard deviation and minimum percentage change for a regression to be reported as anomalous, to improve accuracy further. + +## Outcomes +The primary outcome of my project was three merge requests to [the `PerformanceMonitoring` repository](https://gitlab.cern.ch/atlaspmb/PerformanceMonitoring), totalling a combined ~3600 lines of code changed. +- [`atlaspmb/PerformanceMonitoring!38`](https://gitlab.cern.ch/atlaspmb/PerformanceMonitoring/-/merge_requests/38): The original merge request for the script for uploading all metrics from the most recent nightly build to OpenSearch as part of the existing performance monitoring pipeline +- [`atlaspmb/PerformanceMonitoring!39`](https://gitlab.cern.ch/atlaspmb/PerformanceMonitoring/-/merge_requests/39): Refactors the metric-generation logic to its own file, and includes the anomaly detection, reporting and diagnosis software. +- [`atlaspmb/PerformanceMonitoring!40`](https://gitlab.cern.ch/atlaspmb/PerformanceMonitoring/-/merge_requests/40): Adds a standalone mode to the OpenSearch exporter script that permits it to be manually invoked on a merged database (i.e. one containing metrics from multiple nightly builds) to upload all that history at once. + +Together, these make it possible for the SPOT team to identify and fix regressions more quickly than was previously possible through manual inspection. + +## Further work +Although the anomaly detection pipeline is complete, as with any software project there are areas that could be explored further: +- Implement a missing-data detector, because step-change regressions, which the Bollinger-based univariate detectors pick up, are not necessarily the only kind of anomaly - for example, a bug could cause a crash with no data being reported at all, leading to missing data. I experimented with a missing-data detector but ultimately did not prioritise implementing this. +- The ability to locate the corresponding repository for any components with anomalies would be very useful. +- The orchestration scripts could be migrated from Bash to Python modules so the entire SPOT codebase is in one language and is easier to read and debug. + +## Final reflection +Google Summer of Code 2026 was an incredible program, especially with CERN-HSF. Working on high-energy physics at CERN has been a lifelong dream of mine, and having the opportunity to collaborate in an adjacent area before even completing my undergraduate degree and despite living in a non-Member State is incredible. Only two years ago, I traveled to Switzerland solely to tour CERN, and it feels surreal that code I've written will now be aiding in the operation of the very detector whose control room I visited such a short time ago. I can't wait to see where this path leads, and I'm immensely grateful to both Google and CERN-HSF for making this possible. + +On the more technical side, working on a production-grade HEP codebase was a fantastic opportunity to develop my skills in software development. Although it was challenging at times, I've learnt an enormous amount about performance optimisation, software architecture and industry best practices. Maciej and Tatiana's mentorship and guidance was invaluable, and I'd like to thank them both personally since this project wouldn't have been possible without them. + +## AI Usage +AI was used to a limited extent in this project, principally for research and low-level implementation details. Although I experimented with a number of different models, a common thread was that they were unfamiliar with HEP and would often make incorrect assumptions implicitly, meaning that in most cases reviewing and unit-testing AI-written code was more effort than just writing it myself. I also found most AI models had a strong tendency to produce "spaghetti code" without thought for long-term architecture or maintenance, although stronger models were somewhat more resilient to this. + +## References +[1] [ATLAS Experiment at CERN: Trigger and Data Acquisition](https://atlas.cern/Discover/Detector/Trigger-DAQ) + +[2] [Vazquez, W.P. on behalf of the ATLAS Collaboration: The ATLAS Data Acquisition System in LHC Run 2](https://cds.cern.ch/record/2244345/files/ATL-DAQ-PROC-2017-007.pdf) + +[3] [Mete, A.S., Nowak, M., and van Gemmeren, P. on behalf of the ATLAS Computing Activity: Persistifying the complex event data model of the ATLAS Experiment in RNTuple](https://cds.cern.ch/record/2905189/files/ATL-SOFT-PROC-2024-002.pdf) \ No newline at end of file diff --git a/images/blog_authors/DouglasLindsay.jpg b/images/blog_authors/DouglasLindsay.jpg new file mode 100644 index 000000000..c0c526576 Binary files /dev/null and b/images/blog_authors/DouglasLindsay.jpg differ